
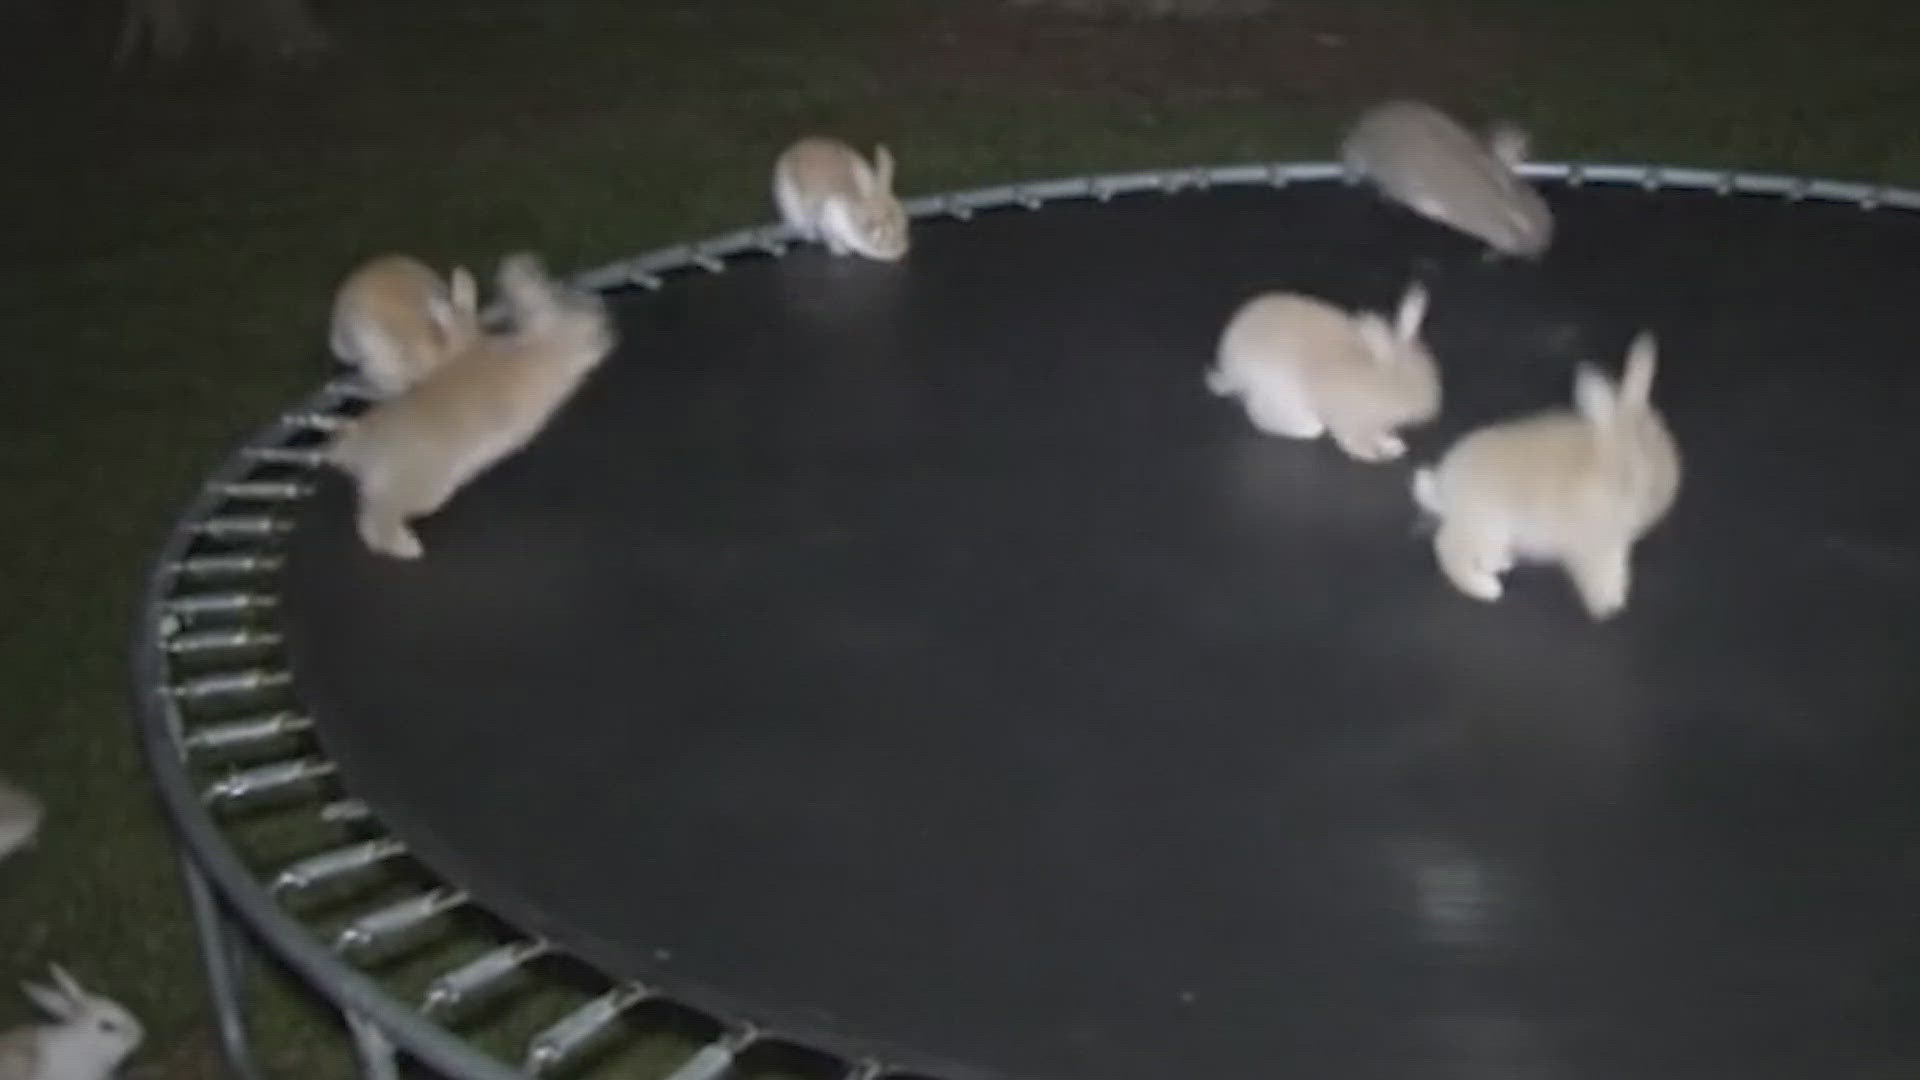
Is the Trampoline Bunnies Video Real or Fake? 5 Visual Clues That Give Away the Ai
The viral bunny clip illustrates the core architectural limits of current generative video models. State-of-the-art tools translate natural language prompts into visual outputs by predicting noise patterns across sequential latent spaces. They do not run a three-dimensional physics engine. The model does not understand mass, gravity, or the tensile strength of an elastic surface; it simply understands that the concept "bouncing" corresponds to an upward trajectory of pixel clusters labeled "rabbit."
This approach produces high surface realism alongside structural absurdity. Fur can look photorealistic down to single hairs because the underlying dataset contains millions of high-definition macro images of mammals. When forced to simulate movement across an unfamiliar boundary, such as an animal interacting with woven industrial mesh, the mathematical representation fails. Spatial coherence collapses at the points where living biology meets mechanical tension.
Researchers tracking synthetic media detection observe that while image-level deepfakes have reached near-flawless static fidelity, video temporal consistency remains unresolved. Movement forces the algorithm to calculate millions of inter-frame dependencies. When multiple entities jump simultaneously, the network takes probabilistic shortcuts, creating merged textures, phantom limbs, and rubbery kinetic motions that give away the synthetic fabrication upon forensic review.



